Thinking loudly about networked beings. Commonist. Projektionsfläche. License: CC-BY
2667 stories
·
144 followers

OpenAI nabs key Patreon execs ahead of upcoming announcement

1 Comment
An illustration of Patreon’s logo.
Patreon co-founder Sam Yam is joing OpenAI to lead Creator Product. | Image: The Verge

OpenAI has hired three former Patreon execs to anchor its product strategy for creators. After starting the creator subscription platform 13 years ago, co-founder and technology chief Sam Yam announced on X that he's joining OpenAI to lead Creator Product. He's also bringing Patreon's former product head Drew Rowny and engineering head Shannon Ma with him on the new venture, both of whom stepped down in the past few weeks.

"We're going to build together with Creators at OpenAI and share early access to a new set of tools that I think will be critically valuable to Creators and their communities," Yam said in his announcement. "Pay attention …

Read the full story at The Verge.

Read the whole story
tante
1 hour ago
reply
Moving from Patreon to OpenAI really shows how little you cared about your previous customer base.
Berlin/Germany
Share this story
Delete

Linke und Antisemitismus: „Die Debatte hat die Funktion, die Linke zu schwächen“

1 Comment
Der Soziologe Peter Ullrich weist Antisemitismusvorwürfe gegen die Linkspartei zurück. Er kritisiert eine rechte Kampagne, die strategisch eingesetzt werde. mehr...
Read the whole story
tante
2 hours ago
reply
"Es wird deutlich, dass diese Debatte die ganz konkrete Funktion hat, die Linke zu schwächen, um Druck auf sie sowie auf SPD und Grüne auszuüben, nicht mit ihr zu koalieren beziehungsweise, um in Koalitionsverhandlungen andere Themen der Linken abzuschwächen. Der Antisemitismusvorwurf wird ganz klar auch strategisch eingesetzt."
Berlin/Germany
Share this story
Delete

Jordan Petridis: The GNOME LLM Policy That I Want

1 Comment

KDE is on the news because of a controversial proposal to define an official “AI” (LLM) policy. Other projects have tried their hand at similar policies and stances but, in my opinion, they miss the mark about the goal of such initiatives. I think that the point of these statements is shaping social norms and not micro-managing developer workflows. They should be about signalling what kind of behavior we want, and what kind we reject.

This proposal does not go into detail about the many problems that LLM have caused to society, workers, the environment. It goes without saying that all these ills are fundamentally opposed to the humanist spirit of GNOME.

With all that in mind, here is what I personally think a GNOME LLM policy could be:

A GNOME Project LLM Policy

The GNOME Project prioritizes the social and human aspects of
collective software creation. Therefore:

1. LLMs ("AI") can not be used to create or modify
code submitted to GNOME, or hosted on GNOME infrastructure.

You might be asked to prove your code meets this requirement.
You might be banned for trying to circumvent this policy.

Example Guidelines for Contributors

These are just a draft of the kind of criteria one could use to evaluate if a submission fits the policy.

  • You must be able to personally reason and explain your changes
  • You must be able to demonstrate knowledge of the problem space you are working on
  • You must solve the underlying issue, not just its symptoms
  • You must respect the time of fellow contributors
  • You must not impersonate yourself through chatbots, agents, or other automated systems

This Is About The Future Of GNOME

GNOME is not just software that happens to ship every six months. That is just a delusion we have been holding up for the last 30 years to keep our loose group of colleagues, friends, and acquaintances, together.

GNOME exists as a collective that find joy in reaching beyond our individual limitations to achieve something bigger. These people, this joy, are the whole point of the project. Contributors are not payroll, a liability, that we hope to downsize next quarter.

“Come do free labor for a handful of corporations by reviewing chatbot output in your free time” is not an attractive proposition to young talented people in 2026. If we want GNOME to continue we need to create an attractive and inviting social space where people are valued as people.

Just like the Foundation is moving to individual donations to stop depending on just a handful of companies, we need to look for the next 100 people that will donate a tiny bit of their time, instead of hoping that corporations will keep 10 overworked engineers on staff. We already have seen how companies will happily abandon a whole chunk of GNOME on a whim.

GNOME is not just software, and it should protect the social and human aspects that make it special. Our success metric is the community and social bonds we create. In the most literal sense GNOME is about the journey and the friends we make along the way.

Free Palestine.

FAQ

How do you enforce this?

You can not. People will still send LLM generated code. This policy makes it explicit that we do not welcome these careless submissions. We have a Code of Conduct that is 80% about telling other people what our values are, and 20% about handling unwanted behavior (“enforcing”). This is similar.

What if people simply lie about not using LLMs?

This is the same problem as authorship, in the copyright sense. Whenever we receive new code we have to assume that “beyond a reasonable doubt” said code has been authored by the person contributing it. We make our best guess. The attached guidelines are a suggestion to make these new guesses.

Ok. But what if people are really good at lying?

This policy is about the majority that will not even try to lie. See previous questions.

Read the whole story
tante
3 hours ago
reply
"GNOME exists as a collective that find joy in reaching beyond our individual limitations to achieve something bigger. These people, this joy, are the whole point of the project."
Berlin/Germany
Share this story
Delete

‘Doom Loop’: OpenAI and Microsoft Admits LLMs Are Destroying the Web and Built on Theft

1 Comment

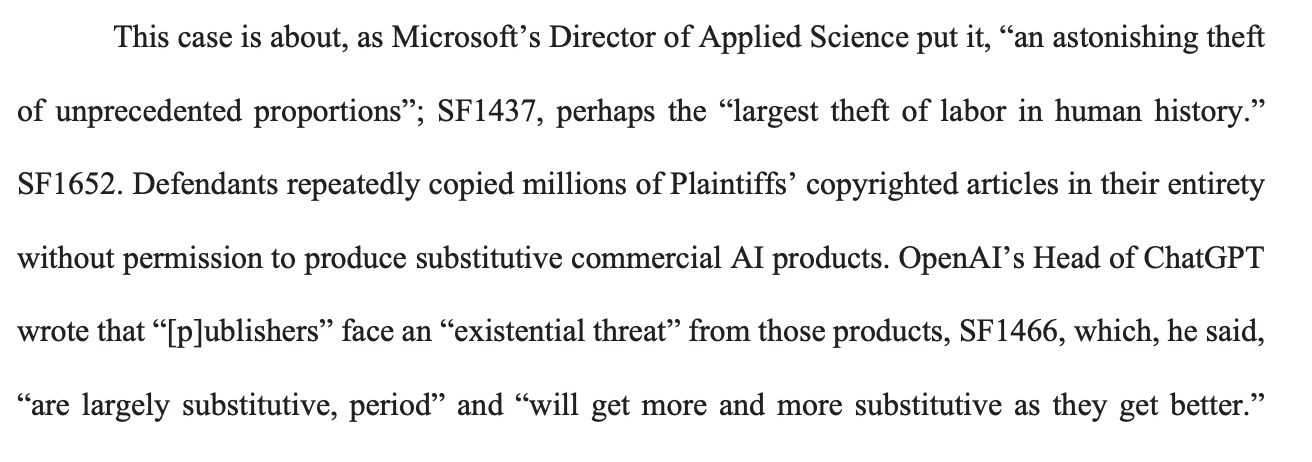
Executives working on AI at Microsoft and OpenAI admitted what its critics have been saying all along: Large language models are predatory pieces of technology that have been built on what a Microsoft executive called “an astonishing theft of unprecedented proportions,” and the “largest theft of labor in human history.” An internal Microsoft document said generative AI products have created a “doom loop” that is killing “the entire web.” 

Those statements and a series of other mask-off moments feature heavily in an unredacted court filing that was unsealed Thursday in the behemoth New York Times vs OpenAI copyright lawsuit that has been winding its way through the court system for years. In a filing asking for summary judgment (basically, a filing with the court asking it to rule), lawyers for the New York Times laid out a series of admissions made by Microsoft and OpenAI executives in documents and depositions that until now had remained either sealed or redacted at the request of Microsoft and OpenAI. 

It’s easy to see why the AI companies wanted to hide this from the public. The statements, taken together, are some of the most damning indictments of the ways LLMs were trained, how they worked, and the immediate threat they pose to human labor. It is a reminder that even as AI becomes more powerful and companies try to shift the narrative to the supposed existential risk of “superintelligent” AI, the tools they have already built were created by stealing from human creativity and labor and are by definition existential threats to the human labor market.

“Millions of people around the world will soon consider large models ‘hoovering up’ all their work to be an astonishing theft of unprecedented proportions,” an internal Microsoft document cited in the case read, adding “almost no one intended for content they created to be used in this fashion, nor are they compensated for its use.”

The filing was written by lawyers for the New York Times but is largely comprised of statements and interviews with big tech executives that admit both that LLMs are largely trained on stolen content, that they represent an existential risk for the human writers, artists, and media companies that they stole from, and that their products have started a “doom loop” that is eating the web and destroying the businesses that these companies stole from. 

The unredacted filing was found by Jason Kint, the CEO of Digital Content Next, a trade organization that represents digital media companies. Kint has been closely following and posting about massive AI copyright lawsuits.

The court filing cites an internal Microsoft document that found that AI products steal from human content creators, then cannibalize clicks from the people and websites they’ve stolen from, thereby destroying their business models. 

“Our AI content strategy has started a ‘doom loop’ that will hurt the performance of our models and the entire web at the same time: It is highly unusual that an end-product threatens the economic foundations of its essential suppliers, but that is the situation we have created for our LLM business with respect to its ‘content supply chain,’” the document said. 

Microsoft executives, including CEO Satya Nadella, testified under oath that after ripping content from the New York Times and other news sites, clicks to those news sites fully cratered, falling by more than 90 percent on Bing. 

Documents obtained during the court proceedings found that OpenAI created “a hack to get around nytimes paywall,” to which OpenAI cofounder Greg Brockman said “ah, nice.” Microsoft executive Brent Hecht wrote that LLMs steal content “without ways of distributing economic value down the supply chain, [which] necessarily threatens the economic stability of those who create the content.” 

OpenAI’s policy director Jack Clark wrote that the company was “creating systems that substitute for the labor of the people that define the ‘culture’ of society” and Microsoft, in a policy document, wrote that generative AI could “significantly disrupt the employment of the very people who generated the data on which the foundation model was trained […] LLMs are a product that destroys its supply chain.” OpenAI called itself an “existential threat” to news publishers, and an OpenAI software engineer testified that “no matter how prominently we show the links, users won’t click.” 

None of this is at all surprising to anyone who has been paying attention to the development of generative artificial intelligence, but the document, taken in whole, is a real they-admit-it situation. OpenAI’s and Microsoft’s lawyers have been trying to argue that their model training is fair use and transformative under copyright law and that they are building something that is fundamentally different from the human labor that it was trained on. But internally, these executives know that what they have built has been built on stolen content and that the products they’ve made are cannibalizing the sources they’ve stolen from and destroying the internet as we know it.   

Read the whole story
tante
5 days ago
reply
"Executives working on AI at Microsoft and OpenAI admitted what its critics have been saying all along: Large language models are predatory pieces of technology that have been built on what a Microsoft executive called “an astonishing theft of unprecedented proportions,” and the “largest theft of labor in human history.” An internal Microsoft document said generative AI products have created a “doom loop” that is killing “the entire web.”"
Berlin/Germany
Share this story
Delete

What kind of Software should we fund?

1 Comment

Laurie Voss, who was one of the founder of NPM, the Javascript package repository that is now run by Microsoft, has written a longer post about an idea about how to fund Free Software that I found interesting. It’s worth reading if you have some time and makes good points even though I will critique it a bit. But financing Free Software is an unsolved problem right now and any meaningful contribution can help us move this forward.

So, let’s dive in Laurie’s idea is quite simple:

We need a way to force companies to pay for Free Software and the package repositories (NPM, PyPI, etc) are the ideal chokepoint to enforce that payment. The package repositories should force companies to pay for access and distribute the money among the packages that were being used:

Second, a fixed slice of that revenue is a royalty, and it goes to the packages. Not to the registry, not to a foundation, not to a grants committee with an application form. Pro rata, to every package that shows up in the paying customer’s dependency trees, weighted by how many paying customers depend on it, automatically, every month

Laurie Voss, https://seldo.com/posts/nobody-pays-for-open-source-we-can-force-them-to/

Now I do think that a few things in the post are smart: Turning charity towards a forced expense for companies makes sense, companies already know how to pay bills and licenses. Also: Understanding package repositories as chokepoints is a clever idea. I also appreciated how he directly addressed the “but people will cheat to game it” argument basically with a “yeah, might happen to a degree, but not doing something cause someone might cheat is not a good strategy” which I think we need to apply a whole lot more when it comes to support systems. Means testing is shit and we shouldn’t do it.

But you know how sometimes you read and argument by someone and it is built well but doesn’t click with you until you realize that their concept of the problem space is very different from yours? This is one of those cases. After I read through the article and thought a bit about it, I had this sort of intrusive thought: “I bet Laurie uses a Mac.”

This is not some FSF-style purity argument or me hating Macs (I do but that’s only cause I have to use one at work and not the matter here). This realization explained to me, why Laurie’s solution didn’t do what I think matters most.

I think Laurie – who as I mentioned in the beginning was one of the founders of NPM – has a very narrow view of Free Software (I keep writing Free Software where Laurie writes Open Source and maybe that is also part of the difference in understanding): To him, Free Software are all the libraries that you (or your “agent” given the hellscape we live in today) can pull into your software project through a package manager such as NPM. And I’d disagree.

Not just cause a lot of those package managers (for example NPM) are run by for-profit companies, though I do think that creates a non-ideal incentive structure. Because what he describes is basically the Spotify sales pitch – at least how many users think about it. Spotify gets money, takes a cut and distributes it among the artists that their users listen to (let’s ignore for a second that that’s not how it works for bullshit reasons and a lot of the money just goes to Taylor Swift). But then Spotify realized that they would have to pay out a lot less money if they created their own music and got that into the playlists. Having that much money flow through a business just to distribute is a recipe for triggering ideas. Like the ones MBAs have. Horrible ideas.

I disagree because that sees Free Software as this backend stack that companies (and if they want to also individuals) build upon. He tries to solve the problem that if you maintain some library in the middle of the JS dependency tree you are basically working for Amazon or Microsoft without a paycheck. And that would do some good, would support a few people who I’d love to have a stable income.

But it also ignores a lot of Free Software that aims (I’d argue) even more at human beings and their needs. You do not install GNOME through NPM or PyPI. It comes with your distribution who put in a lot work into packaging, potentially patching and curating a whole environment for you to be able to use your computer in a more liberating way. It ignores all the infrastructure projects that work outside of the package registry pipeline. Think of all the core C libraries that a modern Linux system is build around. None of them come from any of those package repositories.

Laurie’s idea implicitly frames Free Software as “the underpaid supply chain for startups and big tech” which is partially true, but that’s not the core of it, I’d argue. Some Open Source communities might disagree of course, especially the JavaScript community feels (from the outside) a lot less political than other parts of the Free Software ecosystem. But I think what Laurie’s suggestion really brings forward is the question of what kind of software are important.

All software is important of course. Our data flows through these systems, our infrastructure is built on those countless libraries that are thanklessly being maintained in people’s free time at the expense of sleep. Laurie’s analysis is on point with that. But I am a bit old maybe so when I think about computers I do think about the device people have in front of them. Not just “the services on the Internet that accumulate your data and rent compute back to you” but the thing you start up where your files are. Where you start the tools you want to use to solve a problem at hand, to do a task, to play and have fun.

Obviously he push towards web-based solutions has reshaped computing. “A website with a mobile app and a chrome wrapper for Mac, Windows and maybe Linux” has been turned into the default. everything has a server now that does … something. Often useful things, store your data in a hopefully safe way or provide resources you can’t afford to buy or that wouldn’t be worth buying for the one time you need them. In my impression Laurie thinks about how to fund a world of Chromebooks, of dumb terminals attached to Internet services built on Free Software stacks.

But is that the path that we are 100% happy with? I spent the day on trains from Zurich to Berlin and the wireless fucking sucked. And so much shit just didn’t work. What worked was what I had downloaded before to have available for applications on my machine.

Of course one can argue that cell service and wireless will just get better and that the future is “the Internet + terminal”. But why do we have to subscribe to this understanding of computing that has been defined dominated and pushed by Google, Amazon and Microsoft?

When thinking about how to fund software we quickly end up at the question of what kind of software we want to fund. Not just which single libraries or developers to support but what kinds of structures and systems we want to see in the world.

I think Laurie’s idea is a clever hack to siphon money out of big corporations. I am a big fan. And it would fund a few people who today don’t get funding or who have to have a day job on the side to be able to eat. That is fantastic.

But it is also built around the idea that the kind of computing that big tech has pushed in order to establish chokepoints. Build around the processes that big tech corporations use to build software. And maybe that’s my main irritation.

Package repositories are useful to individual developers. I find a library I could use for something and I can quickly install it. Great. But here’s the question: Am I the target audience of those registries or am I just … kinda there? I think that repositories such as NPM or PyPI are build especially for corporate software development processes. For contractors and developers who have to think about SBOMs and dependency trees to be able to deploy their software to hundreds if not thousands of machines based on a git commit and a successful CI run. DevOps engineers have polished those pipelines to be almost frictionless. They re so polished, that you can even have stochastic parrots use them.

But that is infrastructure for big corporations and their needs. And I am not saying that package repositories are inherently bad, I just wonder if just following those corporate logics is the way. Because setting it up that way does create an implicit pressure towards being a proper cog in the machine that keeps Google’s software supply chain running. They are – after all – directly paying you to use your code.

I think we need to find better solutions to make developing Free Software humane. That does include giving people the resources to be able to learn how to do it and to do it. And the two core resources here are time and money – with time often coming from giving people money so they don’t have to have another job. And that is how we should think about building systems to support and fund the creation and maintenance of Free Software. Not as a way to keep the people Microsoft or some Startup doesn’t want to hire but whose work they’d like to use kinda fed. But as a way to actually create space for human beings to come in and be able to contribute. Regardless of whether your library fits into Big Tech’s supply chain.

Read the whole story
tante
5 days ago
reply
"When thinking about how to fund software we quickly end up at the question of what kind of software we want to fund. Not just which single libraries or developers to support but what kinds of structures and systems we want to see in the world."
Berlin/Germany
Share this story
Delete

Rediscovering The Spark

1 Comment

The last few years have been hard as someone who is not only very much engaged with technologies, their applications, damages and affordances as well as their politics. We’ve been moving through hype cycle after hype cycle with increasing promises at increasing speeds. Which is somewhat natural of course: Being built not around something material, something real, but around a “world-changing narrative” is what defines a hype.

There is the reliance on experts, the hope that they’ll call out what’s going on, point the finger at the issues at hand. But that all only works when there is working journalism that translates and transplants those critiques into the mainstream discourse. Because how else are normal people supposed to be able to have any opinion on how the world is being influenced and reshaped?

I’m not saying that there is no great tech journalism. I am a very happy 404media subscriber for example and there are other sources of great or at least good journalism about tech (when I write “tech” I don’t just mean that as shorthand for “technology” but as a signifier for the digital-technology-industrial-political complex built around Silicon Valley ideology and companies). But the issue is that “technology” is no longer a journalistic vertical, it’s horizontal. Which is a big problem.

There has been this shift (and I am not knowledgeable enough to be able to point at the exact time frame) towards equating “progress” with “technological innovation and development”: Society is moving forward if tech produces more shit. If you’ve heard me talk you might have picked up on me mentioning that today’s vision of the future is just a thinner iPad every few months.

But if “progress” – which is a political term about values that one aims to manifest or express or expand in the world – is just replaced with following PR messages about whatever tech wants to sell next, that does not only make the space of possible futures paperthin, it also puts massive amounts of power into tech’s hands. And I don’t just mean economic and political power (which is also true and needs to change massively, rapidly and aggressively) in this context I mean narrative power.

Let’s look at the last few months. “AI” labs keep releasing basically unsourced accounts about how their stochastic language models are “hacking” or how they are “solving hard math problems”. And sure those would be – if they were true – very important developments. But are we having actual conversations about it outside of very niche circles?

You can use LLMs to run attacks on infrastructure. That’s obvious. A lot of code and howtos describing how to attack services and programs is in the training data so getting an LLM to emit something that might even manage to break into a system isn’t surprising, especially if your are a frontier “AI” lab and can burn more money than god on those experiments. We’ve had exploit frameworks for decades and this just adds to it: A well-funded security researcher can use a string generator to do a more advanced form of fuzzing attack on some service. That is 100% real and does change the threat model of everyone on the internet a bit. But it’s not “OMG AnthrOpenAI’s AI is hacking teh world, Skynet is near!!111”. But that’s where the discourse lands. Because it’s profitable: “AI” Labs can keep their narrative of their LLM having magic powers intact in order to attract more funding to fill the hole in their balance sheet. “Experts” can hit that drum to get invitations to interviews and panels and keynotes about how very scared everyone needs to be.

We end up with everybody scared and badly informed. Because those “AI” models do not plan to hack shit. They don’t do anything without someone prompting them to do something. The issue is that those systems – being stochastic in nature – might go totally off the rails and break something. Or do something interesting. Or just waste a few thousand kWh of energy on nothing really. It’s unpredictable.

But not unpredictable in the way that the discourse these days implies. These systems are not “intelligent”, are not scheming or planing or doing something alien beyond our comprehension. If hooked up to the ability to run code they will run some generated code. Some of it will be absolute garbage and not run, but if the prompt and the moon phase align they might also get to exploit some bug in some – potentially vibe-coded and unreviewed – piece of software.

And that is what’s so toxic about the discourse: We are letting those labs and the boosters of the current hype technology get off the hook without even one relevant question.

Take the recent conversations about how ‘”AI” might kill us all with a 10% possibility’. That’s what a leading person at Anthropic says. And is being reported not as “look, a crank from a weird rationalist cult showed his ass again” but as “Anthropic warns: AI might kill us all”. What the hell are we doing? How can you interview a person who says that and not go *record scratch* “so, you are telling me that your stochastic language model could kill us all with a significant chance and you are still developing it? Are you psychotic?” before going into actually questioning how a synthetic text extruder reasonably would do that.

But tech is progress, tech is the future. So we have to take tech leaders’ mental breakdowns as gospel.

Sure, one can have interviews with OpenAI or Anthropic people about whatever story they are telling us. But you do not need to be an expert to ask: “Okay, but does that even make sense?” You just need a spark of mistrust in authority. And that’s a thing we lost.

We put all our eggs into the tech basket hoping that GoogleAmazonMetaAppleAndWhoeverelse could technologize our problems away. And I am increasingly convinced that the lack of critical analysis of their statements is not just about the many economic pressures that journalists have to operate under, the brutal schedules that allow little time for reflection and thinking. I think that many are scared.

Not scared of what some random technological artifact might do. But scared about challenging tech as the dominant mode of making the future. As soon as you stop taking Dario Amodei or Sam Altman or one of those other unpleasant people serious, you have to start asking yourself where to get your future now. As soon as you stop believing that you need to take Anthropic rationalists or weird freaks working at Meta serious you have to challenge the dominant narrative of tech being the well of progress and future.

And that is scary, I understand that. It would be really easy if every 5 or so years we could just ask some random white boy who went through y-combinator or so about what the future is and just run with it. Okay. Metaverse. Really? If you say so… Oh, Metaverse was not it? Okay, now it’s chatbots. Surely this time it’s gonna be fan-fucking-tastic.

We can spend our limited time on this earth hoping that serial liars like Sam Altman or Elon Musk or whatever their names are surely will not screw us. Or we can go and rediscover the spark of challenging those narratives of the powerful. We have no time to keep idling around in their hellscapish dreams and visions. We need to challenge them. Find better, humane, convivial narratives and need to work towards manifesting them.

And one of the most important things to do is to stop letting those LLM-brainwormed men keep talking about what their magic chatbots will do without challenging their psychotic behavior. If someone really believes that their invention will probably kill humankind and they still happily take their fat paycheck and keep building it, keep demanding more and more resources for that, that person should be forced to have a few months of intense therapy before we let them out into the world again.

Think about a person who works on developing chemicals basically saying: “Yeah we’re just throwing random stuff together. There’s at least a 10% chance that – since we don’t really do any security – we might poison everyone, but please give me all the money you had planned to give to hospitals. KTHXBYE.” The world we currently live in is the one where we respond with “Sure Mr. Altman. Here’s also all the money we wanted to spend on schools.”

That is not a world we should want to be in. Should allow anyone to keep us in. And opening a portal to a better world sounds hard, but the walls between potential worlds are basically just in our heads. We just need to start by breaking the chokehold tech has on the discourse. The spark is still there in each and every one of us.

Read the whole story
tante
8 days ago
reply
"As soon as you stop believing that you need to take Anthropic rationalists or weird freaks working at Meta seriously you have to challenge the dominant narrative of tech being the well of progress and future."
Berlin/Germany
Share this story
Delete
Next Page of Stories